第2章記述統計
2.7 Measures of the Spread of the Data2.7 データの散らばりを表す指標
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation. The standard deviation is a number that measures how far data values are from their mean.
どのデータセットでも重要な特徴の1つが、データのばらつきである。値が平均の近くに密集するものもあれば、平均から広く散らばるものもある。ばらつき、すなわち散らばりの最も一般的な指標は標準偏差である。これは、データの値が平均からどれほど離れているかを測る数値である。
The standard deviation標準偏差
- provides a numerical measure of the overall amount of variation in a data set, andデータセット全体のばらつきの大きさを数値で表す。
- can be used to determine whether a particular data value is close to or far from the mean.あるデータの値が平均に近いか、遠いかを判断するのに使える。
The standard deviation provides a measure of the overall variation in a data set標準偏差は、データセット全体のばらつきを表す
The standard deviation is always positive or zero. The standard deviation is small when the data are all concentrated close to the mean, exhibiting little variation or spread. The standard deviation is larger when the data values are more spread out from the mean, exhibiting more variation.
標準偏差は常に正か0である。データが平均の近くに集中し、ばらつきが小さいと、標準偏差は小さい。値が平均から広く散らばり、ばらつきが大きいと、標準偏差も大きくなる。
Suppose that we are studying the amount of time customers wait in line at the checkout at supermarket A and supermarket B. The average wait time at both supermarkets is five minutes. At supermarket A, the standard deviation for the wait time is two minutes; at supermarket B the standard deviation for the wait time is four minutes.
スーパーAとBで、客がレジの列に並んで待つ時間を調べる。どちらも平均待ち時間は5分である。待ち時間の標準偏差は、スーパーAでは2分、Bでは4分である。
Because supermarket B has a higher standard deviation, we know that there is more variation in the wait times at supermarket B. Overall, wait times at supermarket B are more spread out from the average; wait times at supermarket A are more concentrated near the average.
Bの方が標準偏差が大きいため、待ち時間のばらつきも大きいと分かる。全体として、Bの待ち時間は平均から広く散らばり、Aの待ち時間は平均の近くに集中している。
The standard deviation can be used to determine whether a data value is close to or far from the mean.標準偏差は、値が平均に近いか遠いかを判断するのに使える
Suppose that Rosa and Binh both shop at supermarket A. Rosa waits at the checkout counter for seven minutes and Binh waits for one minute. At supermarket A, the mean waiting time is five minutes and the standard deviation is two minutes. The standard deviation can be used to determine whether a data value is close to or far from the mean.
ローザとビンがともにスーパーAで買い物をするとしよう。ローザはレジで7分、ビンは1分待つ。Aでは平均待ち時間が5分、標準偏差が2分である。標準偏差を使えば、それぞれの値が平均に近いか遠いかを判断できる。
Rosa waits for seven minutes:
ローザは7分待つ。
- Seven is two minutes longer than the average of five; two minutes is equal to one standard deviation.7分は平均の5分より2分長い。この2分は標準偏差1つ分に当たる。
- Rosa's wait time of seven minutes is two minutes longer than the average of five minutes.ローザの待ち時間7分は、平均の5分より2分長い。
- Rosa's wait time of seven minutes is one standard deviation above the average of five minutes.ローザの待ち時間7分は、平均の5分を標準偏差1つ分上回る。
Binh waits for one minute.
ビンは1分待つ。
- One is four minutes less than the average of five; four minutes is equal to two standard deviations.1分は平均の5分より4分短い。この4分は標準偏差2つ分に当たる。
- Binh's wait time of one minute is four minutes less than the average of five minutes.ビンの待ち時間1分は、平均の5分より4分短い。
- Binh's wait time of one minute is two standard deviations below the average of five minutes.ビンの待ち時間1分は、平均の5分を標準偏差2つ分下回る。
- A data value that is two standard deviations from the average is just on the borderline for what many statisticians would consider to be far from the average. Considering data to be far from the mean if it is more than two standard deviations away is more of an approximate "rule of thumb" than a rigid rule. In general, the shape of the distribution of the data affects how much of the data is further away than two standard deviations. (You will learn more about this in later chapters.)
英語のヒント
平均から標準偏差2つ分離れた値は、多くの統計家が「平均から遠い」と考えるちょうど境目にある。2つ分を超えて離れれば遠いとするのは、厳密な規則というより大まかな経験則である。一般に、標準偏差2つ分を超えて離れるデータがどの程度あるかは、分布の形に左右される。(後の章で詳しく学ぶ。)
The number line may help you understand standard deviation. If we were to put five and seven on a number line, seven is to the right of five. We say, then, that seven is one standard deviation to the right of five because 5 + (1)(2) = 7.
数直線を使うと標準偏差を理解しやすい。5と7を数直線上に置くと、7は5の右側にある。5+(1)(2)=7なので、7は5から標準偏差1つ分右にあるという。
If one were also part of the data set, then one is two standard deviations to the left of five because 5 + (–2)(2) = 1.
1もデータに含まれるなら、5+(−2)(2)=1なので、1は5から標準偏差2つ分左にある。
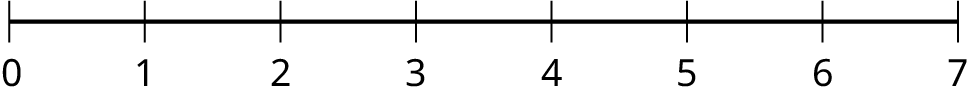

Figure 2.56図 2.56
- In general, a value = mean + (#ofSTDEV)(standard deviation)一般に、値=平均値+(#ofSTDEV)(標準偏差)
- where #ofSTDEVs = the number of standard deviationsここで、#ofSTDEVsは標準偏差何個分かを表す。
- #ofSTDEV does not need to be an integer#ofSTDEVは整数でなくてもよい。
- One is two standard deviations less than the mean of five because: 1 = 5 + (–2)(2).1=5+(−2)(2)なので、1は平均値5より標準偏差2つ分小さい。
The equation value = mean + (#ofSTDEVs)(standard deviation) can be expressed for a sample and for a population.
式「値=平均値+(#ofSTDEVs)(標準偏差)」は、標本と母集団についてそれぞれ表せる。
- sample:標本:
- Population:母集団:
The lower case letter s represents the sample standard deviation and the Greek letter σ (sigma, lower case) represents the population standard deviation.
The symbol is the sample mean and the Greek symbol is the population mean.
The symbol is the sample mean and the Greek symbol is the population mean.
小文字のsは標本標準偏差、ギリシャ文字のσ(小文字のシグマ)は母標準偏差を表す。は標本平均、ギリシャ文字は母平均である。