第8章データ管理
Big Data Analyticsビッグデータ分析
While storage and computing needs have grown by leaps and bounds in the last several decades, traditional hardware has not advanced enough to keep up. Enterprise data no longer fits neatly into standard storage, and the computational power required to handle most big data analytics tasks may take weeks or months, or may be impossible to complete. To overcome this deficiency, many new technologies have evolved to include multiple computers working together, distributing the database to thousands of commodity servers. When a network of computers is connected and works together to accomplish the same task, the computers form a cluster. A cluster can be thought of as a single computer but can dramatically improve the performance, availability, and scalability over a single, more powerful machine at a lower cost by using commodity hardware.
英語のヒント
過去数十年で記憶容量と計算への需要は飛躍的に増えたが、従来のハードウェアの進歩は、それに追い付くほどではなかった。企業データは、もはや標準的なストレージにすっきり収まらない。ビッグデータ分析の仕事の多くを処理するには、計算能力の面から数週間や数か月を要したり、完了が不可能だったりする場合がある。この不足を克服するため、複数のコンピューターを連携させ、データベースを数千台の汎用サーバーへ分散する、多くの新技術が発展した。コンピューターのネットワークが接続され、同じ仕事を達成するために連携すると、それらはクラスターを形成する。クラスターは1台のコンピューターとみなせるが、汎用ハードウェアを使うことで、より強力な単独のマシンより低い費用で、性能・可用性・拡張性を大きく向上させられる。
CONCEPTS IN PRACTICE概念を実践へ
Private Data and Analytics個人データと分析
All social media and search engine websites use data management for machine and deep learning applications. Today there are major concerns related to the use of private data to perform analytics and support targeted sales or broadcast fake news to select customers. Being able to control the use of private data is essential so it does not get manipulated and end up being misused for various reasons. Data compliance is attempting to address this very problem and various regulations have already been put in place in the United Kingdom and Europe via the GDPR regulations. The same is happening in the United States, with regulations being put in place in some states including California in particular.
英語のヒント
すべてのソーシャルメディアや検索エンジンのWebサイトは、機械学習・深層学習のアプリケーションにデータ管理を使っている。今日では、個人データを分析し、対象を絞った販売を支えたり、選ばれた顧客へ偽ニュースを配信したりすることが、大きな懸念となっている。個人データが操作され、さまざまな理由で悪用されることにならないよう、その利用を制御できることが不可欠である。データコンプライアンスは、まさにこの問題へ対処しようとしており、英国と欧州では、GDPRの規制によってすでにさまざまな規制が設けられている。米国でも同じ動きがあり、特にカリフォルニア州を含む一部の州で規制が設けられている。
Analytics Process Model分析プロセスモデル
An analytics process model provides a statistical analysis using a set of processes to solve system problems and find a new market opportunity. There are many sample applications for analyzing data such as risk analytics (e.g., credit scoring, fraud detection), marketing analytics (i.e., using data to evaluate the success of marketing strategies), response modeling (i.e., statistical platform to model the relationship between the customers’ responses and the predicted values), customer segmentation (i.e., dividing the customers into groups with each group sharing the same characteristics to improve the marketing strategy), recommender systems (i.e., a filtering system that provides suggestions for products based on customer rating), and text analytics (i.e., identifying a pattern to understand the data).
英語のヒント
分析プロセスモデルは、一連の過程を使って統計分析を行い、システムの問題を解決し、新たな市場機会を見つける。データ分析の応用例は数多い。たとえば、リスク分析(信用スコアリング、不正検知など)、マーケティング分析(データを使ってマーケティング戦略の成功を評価すること)、応答モデリング(顧客の反応と予測値の関係をモデル化する統計的な基盤)、顧客セグメンテーション(マーケティング戦略を改善するため、同じ特徴を持つ顧客ごとにグループ分けすること)、推薦システム(顧客の評価に基づいて製品を提案するフィルタリングシステム)、テキスト分析(データを理解するためにパターンを見つけること)がある。
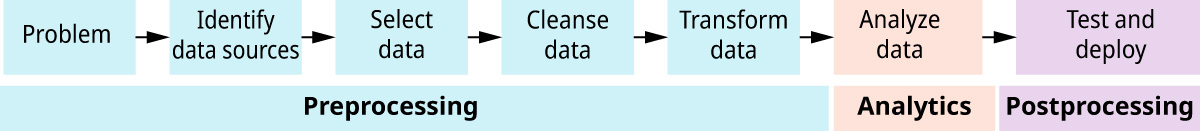
Creating a viable data management infrastructure for analytics applications involves much more than just building a simple machine learning model. It requires an understanding of how all the parts of the enterprise’s ecosystem work together—where/how the data flows into the data team, the environment where the data are processed/transformed, the enterprise’s conventions for visualizing/presenting data, and how the model output will be converted as input for some other enterprise applications. The main goal is to build a process that is easy to maintain and where models are iterated on, the performance is reproducible, and a model’s output can be easily understood and visualized for other stakeholders so that they may make informed business decisions. Achieving those goals requires selecting the right tools as well as an understanding of what others in the industry are doing along with best practices. Figure 8.25 shows the three-stage process of the analytics process model, which we discuss next.
英語のヒント
分析アプリケーションのために実用的なデータ管理基盤を作るには、単純な機械学習モデルを構築するだけでは到底足りない。企業のエコシステムを構成する各部分がどのように連携するかを理解する必要がある。つまり、データがどこから、どのようにデータ担当チームへ流れ込むか、どの環境で処理・変換されるか、企業がデータの可視化・提示にどのような慣行を用いるか、モデルの出力をどのように別の社内アプリケーションの入力へ変換するかを理解しなければならない。主な目標は、保守が容易で、モデルを繰り返し改良でき、性能を再現できる過程を構築することである。また、そのモデルの出力を、ほかの利害関係者が容易に理解し、可視化できるようにして、十分な情報に基づく事業上の判断を支援する。これらの目標を達成するには、適切なツールを選ぶだけでなく、業界のほかの人々が何をしているか、どのような最善の実践方法があるかを理解する必要がある。図8.25は、次に説明する分析プロセスモデルの3つの段階を示している。
attribution: Copyright Rice University, OpenStax, under CC BY 4.0 license · CC BY 4.0 · Source出典
Figure 8.25 The three-stages of the analytics process model are shown. (attribution: Copyright Rice University, OpenStax, under CC BY 4.0 license)
図8.25 分析プロセスモデルの3つの段階を示している。(出典表記:著作権者 Rice University、OpenStax、CC BY 4.0ライセンス)
Data Preprocessingデータの前処理
To preprocess the data, a data scientist may use denormalizing, the merging process, sampling, exploratory analysis, missing values, and outlier detection and handling. The process of merging several normalized data tables into an aggregated, denormalized data table is called denormalizing. The merging process involves selecting information from different tables about a specific entity and then copying it to an aggregated table. Selecting a subset of historical data to build an analytical model is called sampling. The process of summarizing and visualizing data for initial insight is called exploratory analysis. Filling the empty field or deleting it involves resolving a missing value. An outlier is a value outside the population that should be detected in order to apply the handling process on it.
英語のヒント
データを前処理する際、データ科学者は、非正規化、結合処理、標本抽出、探索的分析、欠損値への対処、外れ値の検出と処理を用いることがある。正規化された複数のデータ表を、集約された非正規化のデータ表へ結合する過程を、非正規化という。結合処理では、特定の実体に関する情報を異なる表から選び、集約した表へコピーする。分析モデルを構築するため、過去のデータから部分集合を選ぶことを、標本抽出という。最初の知見を得るためにデータを要約し、可視化する過程を、探索的分析という。空のフィールドを埋めたり、削除したりするには、欠損値への対処が伴う。外れ値は母集団から外れた値であり、それに対する処理を適用するため、検出しなければならない。