第8章データ管理
Data Lake Developmentデータレイクの発展
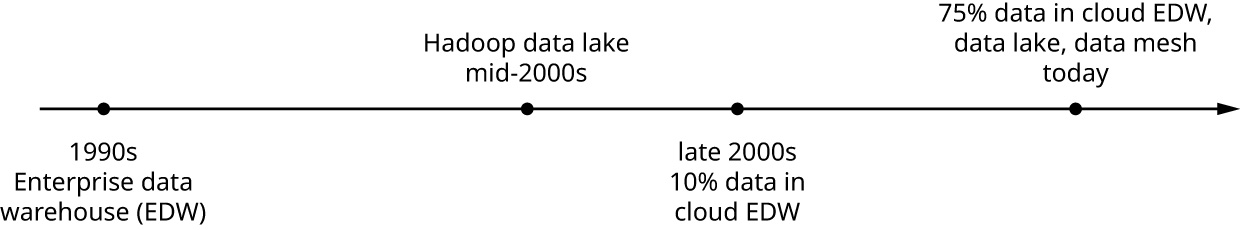
A traditional approach to information management is no longer suitable due to cost and the inability to adapt. Seventy percent of development costs from ETL include an effort to consolidate, prepare, standardize, and transform data for downstream analytics. Costs involve initial capital investment for hardware, software licensing for databases, data integration, and analytics platforms. There is a need to react to emerging changes in the proliferation of data, new and emerging technologies, and cloud-based integrated service platforms. Traditional data storage and analytic tools can no longer provide the agility and flexibility required to deliver relevant business insights and competitive advantage. Figure 8.23 shows the timeline of a data lake.
英語のヒント
従来の情報管理の方法は、費用と、変化に適応できないことのため、もはや適していない。ETLの開発費の70%には、後段の分析に備え、データを集約・準備・標準化・変換する作業が含まれる。費用には、ハードウェアへの初期投資、データベースのソフトウェアライセンス、データ統合、分析プラットフォームがある。データの急増、新しく現れる技術、クラウドの統合サービス基盤に生じる変化へ対応する必要がある。従来の保存・分析の道具では、適切な業務上の知見や競争上の優位性を得るための、機動性と柔軟性をもはや提供できない。図8.23は、データレイクの発展の経過を示す。
attribution: Copyright Rice University, OpenStax, under CC BY 4.0 license · CC BY 4.0 · Source出典
Figure 8.23 An illustration of a data lake shows its evolution from an on-premises tool to a cloud version to a hybrid model. (attribution: Copyright Rice University, OpenStax, under CC BY 4.0 license)
図8.23 オンプレミスの道具からクラウド版、さらにハイブリッドモデルへという、データレイクの発展を示す図。(出典:著作権 Rice University、OpenStax。CC BY 4.0ライセンス)
From Data Lakes to Data Swampsデータレイクからデータスワンプへ
A common challenge with the data lake architecture is that without the appropriate data quality and governance framework in place, when terabytes of structured and unstructured data flow into the data lakes, it often becomes extremely difficult to sort through their content. Data lakes can turn into data swamps as the stored data become too messy to be usable. A data swamp is data stored without organization to make retrieval easy. Many organizations are now calling for more data governance and metadata management practices to prevent data swamps from forming.
英語のヒント
データレイクの構成でよく起こる問題は、データ品質とガバナンスの適切な枠組みが整っていないまま、構造化・非構造化データがテラバイト単位で流れ込むと、中身を整理して調べるのが非常に難しくなることである。保存データが乱雑すぎて使えなくなると、データレイクはデータスワンプ、つまり「データの沼」へ変わり得る。データスワンプは、検索しやすくするための整理をせずに保存されたデータである。多くの組織が現在、その発生を防ぐため、データガバナンスとメタデータ管理の実務をさらに充実させるよう求めている。
LINK TO LEARNING学びを深めるリンク
Data lakes are used to collect very large amounts of both relational and nonrelational data, such as a streaming service collecting data on users’ watching habits, while data warehousing collects relational data, such as when a retailer collects data to use to analyze shoppers’ habits and to control inventory.
英語のヒント
データレイクは、関係データと非関係データの両方を、大量に集めるために使う。たとえば、ストリーミングサービスが利用者の視聴習慣を集める場合である。一方、データウェアハウスが集めるのは関係データである。たとえば小売業者が、買い物客の習慣を分析したり、在庫を管理したりするためにデータを集める場合が当たる。
Where does business intelligence fit into this data system? Business intelligence analyzes this data to help in making decisions. They use data for marketing and targeted sales in particular.
英語のヒント
このデータの仕組みの中で、ビジネスインテリジェンスはどこに位置するのか。データを分析し、意思決定を助ける。特に、マーケティングと、対象を絞った販売に使う。
It can be confusing to understand the ins and outs of each process and how they relate to each other. A blog post about the difference between data lakes, data warehouses, and databases (https://openstax.org/ r/76DataSystems) does a great job of distinguishing each and how each contributes to the use of understanding data.
英語のヒント
各過程の細かな仕組みや、互いの関係を理解するのは、混乱しやすい。データレイク、データウェアハウス、データベースの違いについてのブログ記事(https://openstax.org/r/76DataSystems)は、それぞれを区別し、データの理解と利用へどう役立つかを、うまく説明している。
Business Intelligenceビジネスインテリジェンス
The main goal of the data warehouse is to support decision-making. In order to do that, we need intelligent tools. The set of activities, techniques, and tools aimed at understanding patterns in past data to predict the future is called business intelligence (BI). Modern BI is facilitated through Tableau (https://openstax.org/r/ 76Tableau), ClickView (https://openstax.org/r/76ClickView), and Microsoft Power BI. The quality of data controls the quality of results, which means that bad data gives bad insights (remember GIGO). BI techniques include query and reporting, which provide a graphical user interface (GUI) in which the user can graphically design a report and pivot table, which is a data summarization tool. In addition, one of the BI tools is online analytical processing (OLAP). OLAP is a computer-based approach to analyzing data that enables users to extract and view data from multiple dimensions. It is used to analyze large volumes of data and is commonly used in BI applications. OLAP allows users to perform complex analysis of data by providing a multidimensional view of the data. It can aggregate data across multiple dimensions, such as time, location, product, and customer, enabling users to see trends and relationships that might be hidden in a traditional two-dimensional view of the data.
英語のヒント
データウェアハウスの主な目標は、意思決定を支えることである。そのためには、知的な道具が必要になる。未来を予測するため、過去のデータのパターンを理解しようとする活動・技法・道具の集合を、ビジネスインテリジェンス(BI)という。現代のBIは、Tableau(https://openstax.org/r/76Tableau)、ClickView(https://openstax.org/r/76ClickView)、Microsoft Power BIによって実施しやすくなっている。データの品質が結果の品質を決める。つまり、悪いデータからは悪い知見しか得られない。GIGOを思い出そう。BIの技法にはクエリーとレポート作成があり、利用者が画面上でレポートを設計できるGUIを提供する。また、データの要約に使うピボットテーブルもある。さらに、BIの道具の1つにオンライン分析処理(OLAP)がある。OLAPは、利用者が複数の次元からデータを抽出・閲覧できるようにする、コンピューターによる分析方法である。大量のデータを分析するために使われ、BIアプリケーションによく登場する。データを多次元から見られるようにすることで、複雑な分析を可能にする。時間・場所・製品・顧客など、複数の次元にわたってデータを集約し、従来の二次元の見方では隠れていたかもしれない傾向や関係を見つけられるようにする。