第3章データ構造とアルゴリズム
Selecting a Data Structureデータ構造を選ぶ
Since data representation is a fundamental task in designing algorithms that solve problems, how do we select data structures for a particular problem? Computer scientists apply a top-down approach.
英語のヒント
問題を解くアルゴリズムを設計するうえで、データの表現は基本となる仕事である。では、特定の問題に対して、データ構造をどう選べばよいだろうか。コンピューター科学者はトップダウンの方法を使う。
1. Select an appropriate abstract data type by analyzing the problem to determine the necessary functionality and operations.
1. 問題を分析して必要な機能や操作を決め、適切な抽象データ型を選ぶ。
2. Select an appropriate data structure by quantifying the resource constraints (usually program running time) for each operation.
英語のヒント
2. 各操作の資源制約(通常はプログラムの実行時間)を数値で評価し、適切なデータ構造を選ぶ。
The primary concern is the data and the operations to be performed on them. Thinking back to simple data types like numbers, we focused on addition, subtraction, multiplication, and division as the basic operations. Likewise, to represent complex data types, we also focus on the operations that will most directly support our algorithms. After deciding on an abstract data type, we then choose a particular data structure that implements the abstract data type.
英語のヒント
まず重視するのは、データと、そのデータに対して行う操作である。数のような単純なデータ型を振り返ると、加算、減算、乗算、除算を基本操作として扱った。同様に、複雑なデータ型を表すときも、アルゴリズムを最も直接的に支える操作に注目する。抽象データ型を決めてから、その抽象データ型を実装する具体的なデータ構造を選ぶ。
Linear Data Structures線形データ構造
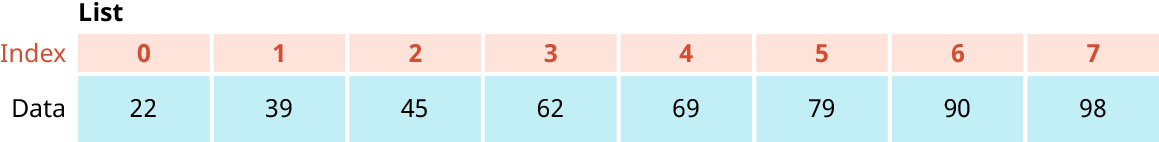
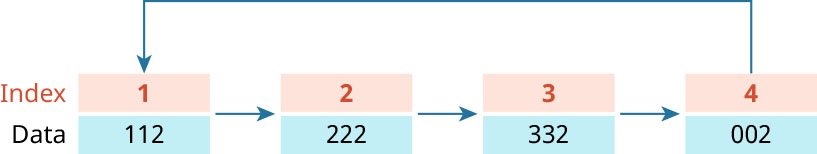
If a problem can be solved with an ordered sequence of elements (e.g., numbers, payroll records, or text messages), the simplest approach might be to store them in a list. Some problems require that actions be performed in a strict chronological order, such as processing items in the order that they arrive or in the reverse order. In these situations, a linear data structure, which is a category of data structures where elements are ordered in a line, is appropriate. There are two possible implementations for the list abstract data type. The first, an array list (Figure 3.3), is a data structure that stores list elements next to each other in memory. The other is a linked list (Figure 3.4), which is a list data structure that does not necessarily store list elements next to each other, but instead works by maintaining, for each element, a link to the next element in the list. Both array lists and linked lists are linear data structures because their elements are organized in a line, one after the other. An advantage of array lists is that they allow (random) access to every element in the list in a single step. This is in sharp contrast with linked lists, which only supports “sequential access.” On the other hand, linked lists support fast insertion and deletion operations, which array lists do not.
英語のヒント
問題を要素(数、給与の記録、テキストメッセージなど)の順序付きの列で解けるなら、リストに保存するのが最も簡単な方法かもしれない。到着順やその逆順に項目を処理する場合など、厳密な時系列順に処理を行う必要がある問題もある。このような状況には、要素を一列に並べる種類のデータ構造である、線形データ構造が適している。リスト抽象データ型には、2つの実装方法がある。1つ目の配列リスト(図3.3)は、リストの要素をメモリ上で隣り合わせに保存するデータ構造である。もう1つの連結リスト(図3.4)は、要素を必ずしも隣り合わせに保存せず、各要素に対して、リスト内の次の要素へのリンクを保持することで動作するリストのデータ構造である。配列リストと連結リストはどちらも、要素を順々に一列に並べるため、線形データ構造である。配列リストの利点は、リストのすべての要素に1回の操作で(ランダムに)アクセスできる点にある。これは「順次アクセス」しかできない連結リストとは対照的である。他方、連結リストでは挿入や削除を高速に行えるが、配列リストではそうはいかない。
attribution: Copyright Rice University, OpenStax, under CC BY 4.0 license · CC BY 4.0 · Source出典
Figure 3.3 An array list stores elements next to each other in memory in the exact list order. (attribution: Copyright Rice University, OpenStax, under CC BY 4.0 license)
図3.3 配列リストは、要素をリストの順序どおりに、メモリ内で隣り合わせに保存する。(出典表記:著作権者 Rice University、OpenStax、CC BY 4.0ライセンス)
attribution: Copyright Rice University, OpenStax, under CC BY 4.0 license · CC BY 4.0 · Source出典
Figure 3.4 A linked list maintains a link for each element to the next element in the list. (attribution: Copyright Rice University, OpenStax, under CC BY 4.0 license)
図3.4 連結リストは、各要素に対して、リスト内の次の要素へのリンクを保持する。(出典表記:著作権者 Rice University、OpenStax、CC BY 4.0ライセンス)
Earlier, we introduced sets as offering less functionality than lists. Both array lists and linked lists can also implement the set abstract data type. Sets differ from lists in two ways: sets are unordered—so elements are not assigned specific positions—and sets only consist of unique elements. In addition to implementing sets, linear data structures can also implement the map, priority queue, and graph abstract data types. If linear data structures can cover such a wide range of abstract data types, why learn other data structures? In theory, any complex data can be represented with an array list or a linked list, although it may not be optimal, as we will explain further.
英語のヒント
先に、集合はリストよりも機能が少ないものとして紹介した。配列リストでも連結リストでも、集合抽象データ型を実装できる。集合とリストには2つの違いがある。集合には順序がないため、要素には特定の位置が割り当てられない。また、集合は重複しない要素だけで構成される。線形データ構造は、集合に加え、マップ、優先度付きキュー、グラフの抽象データ型も実装できる。これほど多様な抽象データ型を線形データ構造で扱えるのなら、なぜほかのデータ構造を学ぶのだろうか。理論上は、どのような複雑なデータも配列リストや連結リストで表現できる。ただし、後で詳しく説明するように、それが最適とは限らない。
One drawback of relying only on linear data structures is related to the concept of efficiency. Even if linear data structures can solve any problem, we might prefer more specialized data structures that can solve fewer problems more efficiently, and help represent real world data arrangements more closely. This is particularly useful when we have large amounts of data like places or roads in an online map of the entire world. Linear data structures ultimately organize elements in a line, which is necessary for implementing lists but not necessary for other abstract data types. Other data structures specialize in implementing sets, maps, and priority queues by organizing elements in a hierarchy rather than in a line.
英語のヒント
線形データ構造だけに頼ることの欠点の1つは、効率という概念に関わる。線形データ構造でどの問題も解けるとしても、対応できる問題は少なくても、より効率よく解け、現実世界のデータの配置をより忠実に表せる、特化したデータ構造のほうが望ましいことがある。世界全体のオンライン地図の場所や道路のように、大量のデータを扱うときには、とりわけ有用である。線形データ構造では結局、要素を一列に並べる。これはリストの実装には必要だが、ほかの抽象データ型には必要ない。ほかのデータ構造は、要素を一列ではなく階層に整理することで、集合、マップ、優先度付きキューの実装に特化している。